Thursday, September 5, 2013

Treating Environments Like Code Checkouts

In our business, the term "environment" is rather overloaded. It's used in so many contexts that just defining what an environment is can be challenging. Let's try to feel out the shape...

We are in business providing some sort of service. We write software to implement pieces of the service we're offering. This software needs to run someplace. That someplace is the environment.

In traditional shrink wrap software, the environment was often the user's desktop, or the enterprise's data center. The challenge then was to make our software be as robust as possible in hostile environments over which we had little control.

The next step on the evolutionary ladder was the appliance. Something we could control to some extent, but it still ends up sitting on a location and in a network outside our control.

The final step is software as a service, where we control all aspects of the hosts running our applications.
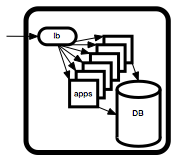

From a build and release perspective, what matters is what we can control. So it makes sense to define an environment as a set of hardware and software assembled for the purpose of running our applications and services.

A typical environment for a web service might look like the diagram on the right.

So an environment is essentially:
       Hardware
          OS
   Third Party Tools
       Our Apps
  + Configuration
====================
      Environment
When we develop new versions of our software, we would like to test it someplace before we inflict it on paying customers. One way to do that is the create environments in which the new version can be deployed and tested.

A big concern is how faithfully our testing environment will emulate the actual production environment. In practice, the answer varies wildly.

In the shrink wrap world, it is common to maintain a whole bank of machines and environments, hopefully replicating the majority of the setups used by our customers.

In the software as a service world, the issue is how well we can emulate our own production environment. For large scale popular services, this can be very expensive to do. There are also issues around replicating the data. Often, regulatory requirements and even common sense security requirements preclude making a direct copy of personally identifiable data.

This being said, modern virtualization and volume management addresses many of the issues encountered when attempting to duplicate environments. It's still not easy, but it is a lot easier than it used to be.

If you have the budget, it is very worthwhile to automate the creation of new environments as clones of existing ones at will. If you can at least achieve this for 5-7 environments, you can adopt an iterative refinement process, very similar to the way you manage code in version control systems.

We start by cloning our existing production environment to create a new release candidate environment. This one will evolve to become our next release.

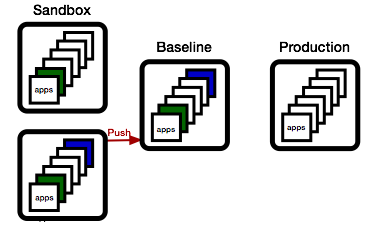
To update a set of apps, we first again clone the release candidate environment, creating a sandbox environment to test both the deploy process and the resulting functionality.

Then, we deploy one or more updated applications, freshly built from our continuous build service (aka Jenkins, TeamCity, or other).

The technical details on how the deploy happens are important, but not the central point here. I first want to highlight the workflow.


Now, let's suppose a different group is working on a different set of apps at the same time.

They will want to do the same: create their own sandbox environment by cloning the release candidate environment, then adding their new apps to it.

Meanwhile, QA has been busy, and the green app has been found worthy. As a consequence, we promote the sandbox environment to the release candidate environment.
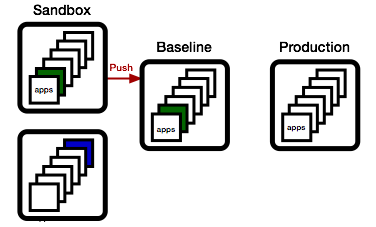
We can do this because none of the apps in the current release candidate are newer than the apps in the sandbox.

Now, if the blue team wishes to promote their changes, they first need to sync up. They do this by updating their sandbox with all apps in the baseline that are newer than the apps they have.
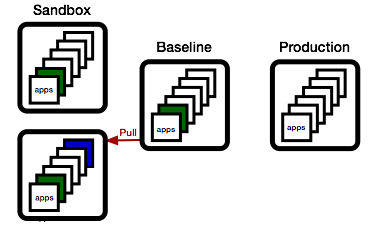
... and if things work out, they can then promote their state to the baseline.

 
... and if the baseline meets the release criteria, we push to production.
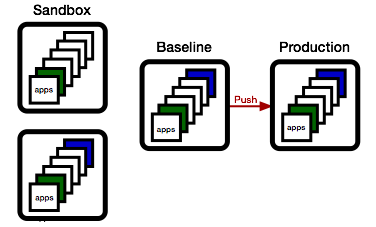
Note that at this point, the baseline matches production, and we can start the next cycle, just as described above.

This process should feel very familiar. It's nothing else but the basic change process as we know it from version control systems, just applied to environments:
  • We establish a baseline
  • We check out a version
  • We modify the version
  • We check if someone else modified the baseline
  • If yes, we merge from the baseline
  • We check in our version.
  • We release it if it's good.

Tuesday, August 20, 2013

Dear Reader...

Hello there!

There aren't that many of you, so thanks to those who took the time to come.

I've been wondering what I can do to make this more interesting. Looking at the stats, it does appear that meta-topics are most popular:
That is interesting, since I would have thought that more detailed "how to" articles would be better.

Another thing I wonder about is the lack of direct response. Partly, that's because there just aren't that many folks interested in the topic, but maybe it's also the presentation.

I find that the most difficult part of my job isn't the technical aspect, it's the communication aspect. I often oscillate between saying things that are obvious and trivial, and saying things that have more controversy hidden that it appears at first, and people often only realize at implementation time what the ultimate effect of a choice is.

An important motivation for this blog is to practice finding the right level, so feedback is always appreciated.

... and yes, I need to post more stuff ...

Sunday, July 21, 2013

Major Version Numbers can Die in Peace

Here's a nice bikeshed: should the major version number go into the package name or into the version string?

A very nice explanation of how this evolved: http://unix.stackexchange.com/questions/44271/why-do-package-names-contain-version-numbers

Even though it is theoretically possible to install multiple versions of the same package on the same host, in practice this adds complications. So even though rpm itself will happily install multiple versions of the same package, most higher level tools (like yum, or apt), will not behave nicely. Their upgrade procedures will actively remove all older versions whenever a newer one is installed.

The common solution is to move the major version into the package name itself. Even though this is arguably a hack, it does express the inherent quality of incompatibility when doing a major version change to a piece of software.

According to the semantic versioning spec, a major version change:
Major version X (X.y.z | X > 0) MUST be incremented if any backwards incompatible changes are introduced to the public API
A new major version will break non-updated consumers of the package. That's a big deal. In practice, you will not be able to perform a major version update without some form of transition plan, during which both the old and the new version must be available.

Note that you can make different choices. A very common choice is to maintain a policy of always preserving compatibility to the previous version. This gives every consumer the time to upgrade.

In either case, there is no need to keep the major version number in the version string. If you're a good citizen and always maintain backwards compatibility, your major version is stuck at "1" forever, not adding anything useful - and if you change the package name whenever you do break backwards compatibility, you don't need it anyways...

So, how about finding a nice funeral home for the major version number?

Friday, July 5, 2013

What's a Release?

I recently stumbled over the ITIL (Information Technology Infrastructure Library), a commercial IT certification outfit which charges 4 figure fees for a variety of "training modules", with a dozen or so required to earn you a "master practitioner" title...

Their definition of a release is:
A Release consists of the new or changed software and/or hardware required to implement approved changes. Release categories include:
  • Major software releases and major hardware upgrades, normally containing large amounts of new functionality, some of which may make intervening fixes to problems redundant. A major upgrade or release usually supersedes all preceding minor upgrades, releases and emergency fixes.
  • Minor software releases and hardware upgrades, normally containing small enhancements and fixes, some of which may have already been issued as emergency fixes. A minor upgrade or release usually supersedes all preceding emergency fixes.
  • Emergency software and hardware fixes, normally containing the corrections to a small number of known problems.
Releases can be divided based on the release unit into:
  • Delta release: a release of only that part of the software which has been changed. For example, security patches.
  • Full release: the entire software program is deployed—for example, a new version of an existing application.
  • Packaged release: a combination of many changes—for example, an operating system image which also contains specific applications.
Even though this definition does pretty much represent a consensus impression of the nature of a release, I think the definition, besides being too focused on implementation details, places too much emphasizes on "change".

Obviously, when viewing a succession of releases, it makes a lot of sense to talk about deltas and changes, but that is a consequence of producing many releases and not part of the definition of a single release.

A release is a snapshot, not a process. The question should be: "what is it that distinguishes the specific snapshot we call a release from any other snapshot taken from our software development history?"

The main point is that the release snapshot has been validated. A person or a set of people made the call and said it was good to go. That decision is recorded, and the responsibility for both the input into the decision and the decision itself can be audited.

In theory, every release should be considered as a whole. In practice, performing complete regression testing on every release is likely to be way too expensive for most shops. This is the reason for emphasizing the incremental approach in many release processes.

There is nothing wrong with making this optimization as long as everyone does it in full awareness that it really is a shortcut. Release managers need to consider the following risk factors when making this tradeoff between speed and precision:
  • Do I really know all the dependencies in order to evaluate the effect of a single change?
  • Do I really understand all the side effects?
  • Do all the stakeholders understand and agree with the risk assessment?
The ITIL discussion of the difference between major/minor/emergency really reflects the different ways stakeholders go about validating a release.

The ITIL discussion about packaging really means that a release is published, released out of the direct control of the stakeholders.

Incorporating these two facets results in my version of the definition of a release as:
A validated snapshot published to a point of production with a commitment by the stakeholders to not roll back.
I think this captures the essence better:
  • A release is a state, not a change.
  • A release represents a commitment by the stakeholders.
  • A release is published, which really means it has escaped the from the control of the stakeholders. Outsiders will see what is, and there is nothing the stakeholders can do about it.
To be fair, the ITIL definition isn't really that far off: replace "approved set of changes" with "approved set of features", and we're pretty much in agreement. But the tone makes the music, and the emphasis on state instead of change forces the discussion to always be about the whole product, and separates the "what we want" from the "how do we get it".

Saturday, June 1, 2013

Mission Creep

I just discussed a simple perishable lock service, and of course the usual thing happens: mission creep.

It turns out QA wants to enforce "code freeze", aka no more deploys to certain test environments where QA is doing their thing.

At first, besides being a reasonable requests, it is amazingly easy to add on to the code. Instead of setting the expiration date to "now", we set it to some user specified time, possible way into the future.

But we are planting the seeds of doom....

Remember the initial assumptions of "perishable" locks... that is they are perishable.

In other words, we assume that the lock requester (usually a build process) is the weak link in the chain, and is more likely to die than the lock manager. And since ongoing builds essentially act as a watchdog for the lock manager (i.e. if builds fail because the lock manager crashed, folks will most certainly let me know about it), I can be relatively lax and skimp on things like persisting the queue state. If the lock manager crashes, so what: some builds will fail, somebody is going to complain, I fix and restart the service, done.

But now suddenly, QA will start placing locks with an expiration date far into the future. Now, if the lock manager crashes, it's not obvious anyone will notice immediately. Even if someone notices, it's not clear they will be aware of the state it was in prior to the crash, so there is a real risk of invalidating weeks of QA work.

So, what am I to do?
  • Ignore the problem (seriously: there is a risk balance that can be theoretically computed: the odds of a lock manager crash (which increases, btw, if you add complexity) vs the cost of QA work lost).
  • Implement persistence of the state (which suddenly adds complexity and increases the probability of failure - simplest example being: "out of disk space")
  • Pretend QA is just another build, and maintain a keep-alive process someplace.
The last option appears attractive, as it will not require modifying the lock service itself, but truth be told, it is simply moving the complexity of the problem elsewhere. Now you need to worry about keeping the keep-alive process alive... fun fun...

So what would you do?

Wednesday, May 29, 2013

Annotating Git History

As is well known, git history is sacred. There are good reasons for it, but it does make it difficult sometimes to correct errors and integrate git into larger processes.

For example, it is very common to include references to issue tracking systems in git commit comments. It would be nice if one could mine this information from git in order to update the issues automatically, for example at build time or at deploy time.

Unfortunately, we're all human and make mistakes. Even if you have validation hooks and do the best possible effort, invalid references or forgotten references make it difficult to rely on the commit comments.

It would be nice if it was easier to fix old git commit comments, but history being immutable is one of the core concepts baked into git, and that's a good thing. So I went for a different solution.

How about attaching annotated git tags to commits? That would preserve the history while adding annotations with newer information. The only trouble with this is that the current git commands aren't very good at revealing this information to casual git users.

The convention I currently use is quite simple: attach a tag whose name begins with CANCEL to the commit to be updated.

Let's say we wish to correct this commit:
% git log -1 5a434a
commit 5a434ac808d9a5c10437b45b06693cf03227f6b3
Author: Christian Goetze <cgoetze@miaow.com>
Date:   Wed May 29 12:57:57 2013 -0700

    TECHOPS-218 Render superceded messages.
Attach the tag, like this:
% git tag -m "new commit message" CANCEL_5a434a 5a434a
Now, the build and deploy scripts can mine this information. They start by listing all the tags attached to the commit:
% git show-ref --tags -d \
     | grep '^'5a434a \
     | sed -e 's,.* refs/tags/,,' -e 's/\^{}//'
Then, for every tag, we check whether it's an annotated tag:
% git describe --exact-match CANCEL_5a434a
CANCEL_5a434a
Note that this command fails if it's a "lightweight" tag. Once you know it's an annotated tag, you can run:
% git cat-file tag CANCEL_5a434a
object 5a434ac808d9a5c10437b45b06693cf03227f6b3
type commit
tag CANCEL_5a434a
tagger Christian Goetze <cgoetze@miaow.com> 1369865583

new commit message
This is easy to parse, and can be used as a replacement for the commit comment.

And what if there is another error in the annotation? Simply add another tag with the correction. The number in red above is the unix timestamp expressed as seconds since 1970, so you can sort the annotations by time and just take the latest.

By the way, if anyone knows a nicer way to show all tags attached to a specific commit, please let me know.

Friday, May 17, 2013

Reinventing a Wheel: Hierarchical Perishable Locks

I've written before about the perennial build or buy dilemma, and here it is again.

I was desperate for a solution to the following kinds of problems:
  • I have a bunch of heavyweight tests running in parallel, but using the same database. These tests unfortunately tend to create a mess, and every once in a while the database needs to be reset. During the reset, no access by automated tests should be permitted.
  • Integration and UI tests run against a deployed version of the software. Most of these tests can be run concurrently, but not all - but more importantly, none of those tests will deliver a reliable result if a new deploy yanks away the services while a test against them is running. (yes, I know, they should be "highly available", but they aren't, at least not on those puny test environments).
This cries out for some sort of locking mechanism.

Ideally, it should be a hierarchical locking mechanism to support controlled sharing for concurrent tasks, while still being able to lock the root resource.

If you use naive methods, you are likely to get hurt in several ways:
  • Builds are fickle. They fail, crash or get killed by impatient developers. Any mechanism that requires some sort of cleanup action as part of the build itself will not make you very happy.
  • Developers have a strong sense of fairness and will get impatient if some builds snag a lock right out from under their nose. So we need a first come first serve queuing mechanism. 
  • If you use touch files with timestamps or some similar device, you run up against the lack of an atomic "test and set" operation, and also run the risk of creating a deadlock.
I've googled and searched, and even though I found lots of interesting papers, I haven't found anything remotely close to what I wanted. Most systems I found solve problems way more complicated that what I want here.

I'm sure that the moment I hit publish, I'll locate the original wheel hiding in plain sight someplace. Maybe some kind reader will reveal it for me...

Meanwhile, I have something that works.

The basic idea is simple:
  • My services keeps a hash (or dict) of queues.
  • Every time someone requests a resource, the queue for that resource is either created from scratch, or, if it already exists, searched for an entry by the same requester. 
  • If the request is already in the queue, a timestamp in the request is updated, otherwise the the request is added at the end of the queue.
  • If the request is first in line, we return "ok", otherwise we return "wait".
  • In regular intervals, we go through all queues and check if the head item has timed out. If yes, we remove it, and check the next item, removing all the dead items until we find an unexpired one, or until the queue is empty.
  • If a request to release an resource comes in, we check the queue associated with the resource and set the timestamp to zero. This will cause the request to be automatically purged when it comes up.
This is about 100 lines of code in node. Even though node is quite controversial, it is ideally suited for the task at hand:
  • The event loop model ensures my code "owns" the data while processing a request. No shared memory or threading issues.
  • The requests and responses are very short, so no hidden traps triggered by folks submitting megabyte sized PUT requests .
  • The queues tend to be short, unless you have a big bottleneck, which really means you have other problems. This means that processing the requests is essentially constant time. A large number of resources is not really a problem, since it is easy to shard your resource set.
Adding hierarchical locks to this service is relatively simple. We only need to change two things:
  • We introduce shared vs exclusive locks. Shared locks have many owners, each with their own timestamp. When enqueuing a shared lock, we first check if the last element in the queue is also a shared lock, and if yes, we merge it instead of adding a new lock to the queue.
  • We introduce resource paths, and request an exclusive lock for the last element in the path, but shared locks for all the parent elements.
This appears to give us the right behavior. So, in our database example at the beginning, the tests would each say:
grab mydatabase/mytest
This will create a shared lock on mydatabase, and an exclusive lock on mydatabase/mytest.

If the lock holder reaches the front of both queues, then the grab request will succeed, and the task can proceed.

If another task comes along and requests:
grab mydatabase/yourtest
then the shared lock request for mydatabase is merged, and that task will also be at the head of the queues for all of its resources, and can proceed.

Now, if the big database cleanup task comes along, it will just say:
grab mydatabase
Since mydatabase here is at the end of the resource path, it will request an exclusive lock which will not be merged with the previous ones, but queued after them. The cleanup task will have to wait until all of the owners of the shared lock release their part, and only then can it proceed.

Should one of the test tasks decide to give it a try, they will again end up requesting a shared lock on mydatabase. Since a shared lock cannot be merged with an exclusive lock, the new shared lock will be queued after the exclusive lock, and the test task will have to wait until the cleanup task is done. Fairness is preserved, and it appears that we have all the right properties....

Code is here - please be gentle :)